 Image: Antoine Taveneaux, CC BY-SA 3.0
Why so many things are bell-shaped, and why some are not
Measure the heights of a thousand adult men in any country and draw the histogram. You get a bell: a hump near 175 cm, symmetric, thinning out to almost nothing beyond 150 and 200. Do the same with the errors of a thousand careful measurements of anything, or the marks on a long exam, or the weights of a thousand eggs from one farm, and you get the same shape. It is so common that the curve is called the normal distribution, as if everything else were abnormal.
Then measure the sizes of a thousand cities, or the magnitudes of a thousand earthquakes, or the fortunes of a thousand households. The histogram is nothing like a bell. Most values are small, a few are enormous, and the enormous ones are not rare enough to ignore. Both facts need an explanation, and the explanations are different.
Where the bell comes from
The reason for the bell is a theorem, and it says this: add up many independent random quantities, none of which dominates the sum, and the distribution of the total is close to the normal curve, whatever the distribution of the individual pieces. This is the central limit theorem. Abraham de Moivre found the first case in 1733, for the number of heads in many coin tosses, and Pierre-Simon Laplace proved the general version in 1810.
The theorem explains height. An adult's height is the sum of a great many small contributions: thousands of genetic variants each adding or subtracting a fraction of a millimetre, plus nutrition in each year of childhood, plus illnesses, plus chance. No single one dominates. The sum is normal, because sums are. It explains measurement error for the same reason: an error is the sum of many small disturbances, the temperature of the instrument, the tremor of the hand, the rounding of the scale.
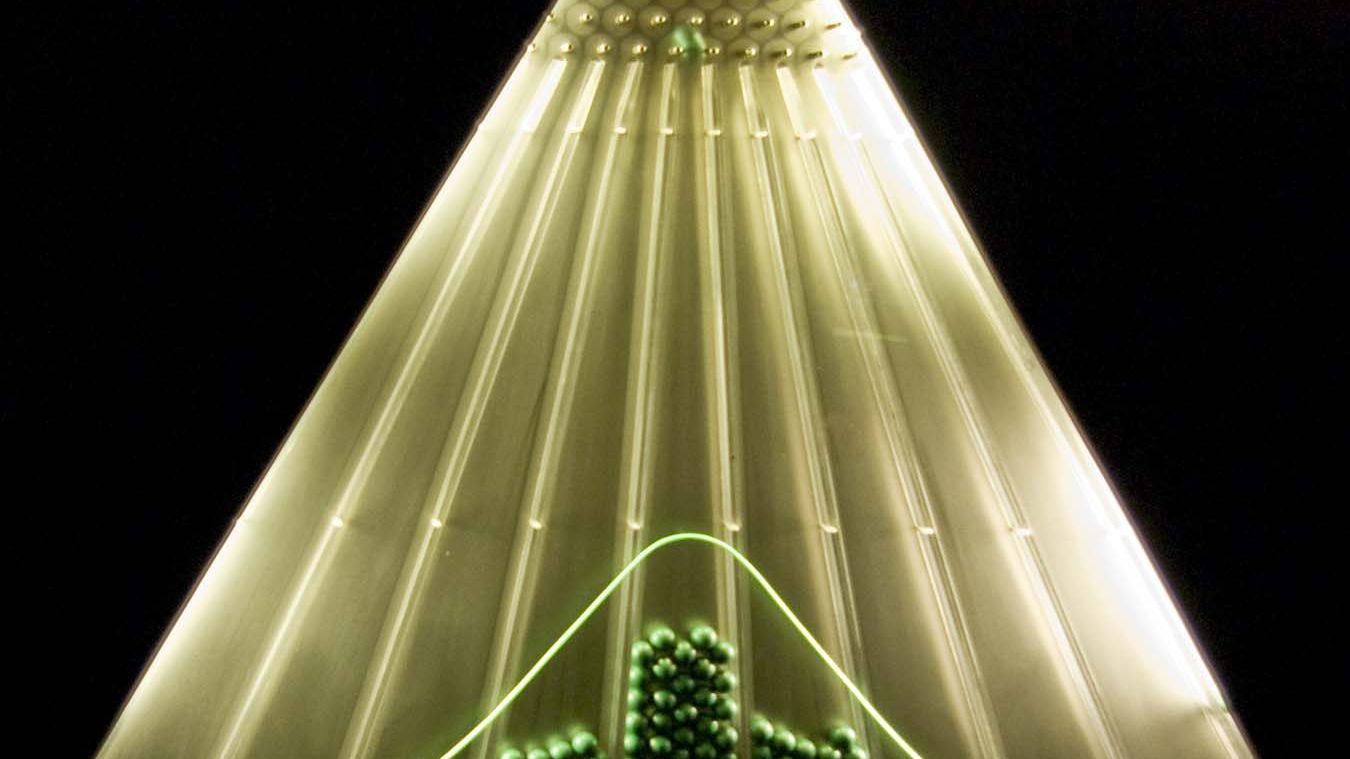
The Galton board shows the theorem happening. Balls fall through rows of pins, bouncing left or right at each pin with equal chance, and collect in slots at the bottom. A ball's final position is the sum of a dozen coin tosses, left counting minus one and right plus one. With one row of pins there are two slots and the piles are equal. With twelve rows the piles form a bell, and the more rows, the smoother the bell. Francis Galton built the first one in the 1870s to make exactly this point, and Unit 5 of the Statistics Masterclass has an interactive one you can run with any number of rows and watch the shape appear.
The theorem has a condition that matters: the pieces must be added. Where they are multiplied, the result is different, and we come to that.
Why statisticians care so much
The central limit theorem is also the reason the mean of a sample behaves so well. A sample mean is a sum of observations divided by \(n\), so whatever the population looks like, skewed incomes or lumpy counts, the mean of a large enough sample is approximately normal around the population mean, with a spread of \(\sigma/\sqrt{n}\). Every confidence interval and every test on a mean in the first half of a statistics course rests on that fact. The usual rule of thumb says 30 observations are enough; for a badly skewed population it takes more, and Unit 5 shows how many with real data.
Where the bell fails
Now the cities. The largest city in most countries has several times the population of the second, which has more than the third, and so on down a long tail of small towns. If city sizes were normal, a country with a mean city size of 100,000 and a standard deviation of 50,000 would essentially never have a city above 400,000, six standard deviations out. Every country has one. The distribution of city sizes follows, roughly, a power law: the number of cities larger than \(x\) falls like \(1/x\). Doubling the size threshold halves the count, at every scale, with no bell and no characteristic size.
Earthquakes obey the same kind of law, called the Gutenberg-Richter relation: each step of one unit in magnitude is about ten times rarer than the step below, and since a step of one unit is about 32 times the energy, the biggest earthquake of a century releases more energy than all the small ones put together. Wealth follows a power law in its upper tail, which Vilfredo Pareto noticed in 1896; word frequencies follow one, which George Zipf made famous; so do the sizes of files on a disk, the citations of papers, and the number of followers of social media accounts.
These distributions are called heavy-tailed, because the probability of an extreme value falls off slowly, as a power of \(x\), rather than fast, as the normal's \(e^{-x^2}\). For a heavy-tailed quantity the mean of a sample can be dominated by its single largest value, the standard deviation may not even exist in the limit, and the central limit theorem's reassurance about sample means weakens or disappears. Averaging a thousand household incomes gives a figure that moves a lot when one billionaire joins the sample, and that is why incomes are summarized by the median.
Why these are different
The central limit theorem needs sums of pieces of comparable size. Heavy tails arise where that condition fails. One route is multiplication: if a quantity grows by a random percentage each year, its logarithm is a sum and is therefore normal, so the quantity itself has a log-normal distribution, which is skewed with a long right tail. Incomes in the middle of the range look like this. Another route is a process in which the large grow faster: cities attract migrants in proportion to their size, papers get cited because they are cited, and that proportional growth produces power laws. A third is a physical cascade, as in earthquakes, where a small slip can trigger a large one.
Telling a true power law from a log-normal or from an exponential with a long tail is a real statistical problem, and claims of power laws in the literature have often been made from a straight-looking line on a log-log plot and nothing else. Aaron Clauset, Cosma Shalizi, and Mark Newman tested 24 such claims properly in 2009, using maximum likelihood and goodness-of-fit, and found that in many of the datasets the power law was no better than the alternatives. Their paper is free and is the research spotlight of Unit 4 of the Statistics Masterclass.
The practical rule
Before using the normal distribution, ask whether the quantity is a sum of many small things or the product or outcome of something that feeds on itself. Heights, errors, test scores, and averages of large samples are sums. Incomes, city sizes, insurance claims, earthquake energies, stock market crashes, and the sizes of forest fires are not, and for those the bell curve will tell you that a catastrophe is impossible shortly before it happens. The financial models of 2007 that called a daily move of 25 standard deviations a once-in-the-age-of-the-universe event had made exactly this mistake.
Unit 4 of the Statistics Masterclass introduces the normal distribution and the heavy tails of earthquakes side by side, and Unit 5, which is free to read, proves the central limit theorem's practical form and checks it on real measurements. The dataset of the week for Unit 4 is the earthquake catalogue of the United States Geological Survey, where you can draw the histogram of magnitudes yourself and see how far from a bell it is.